Choose a topic
We consider cost, safety, compliance, and how the idea can be meaningfully tested.
Independent experiment log
AI, software, web services, game development, automation, and online business. We test ideas found online and document what happened, along with the conditions and process.
Ideas found online, tested in the real world.
FIELD NOTES / EXPERIMENT LOG
Records of rumors and ideas we tested for real under fixed conditions. What did not work stays in the record too.
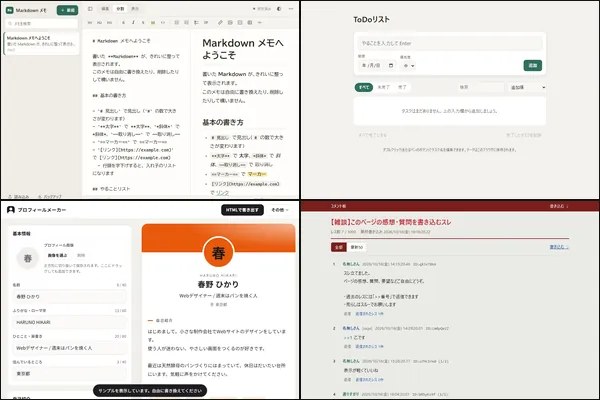
Login, contact form and AI chat included: no problems found, and some safeguards nobody asked for. The apps are here to try.
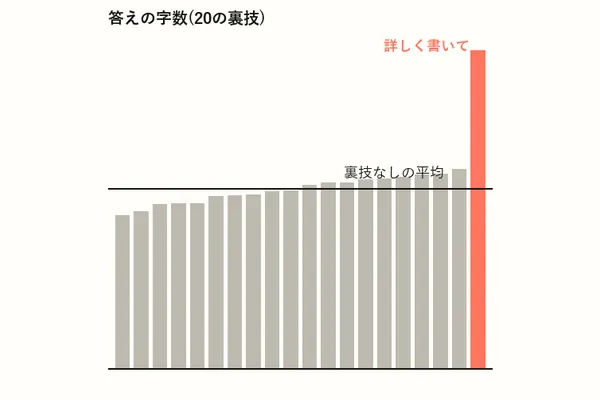
Tips, deep breaths, threats, expert roles: 20 widely shared tricks, 66 runs under identical conditions. Only “write in detail” clearly changed the answers.
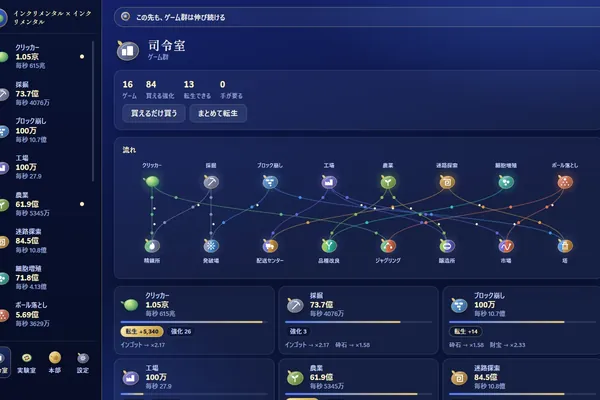
Notes from building a 16-game idle game in three days with Claude Code: where it got stuck and what fixed it. The game is playable in the browser.
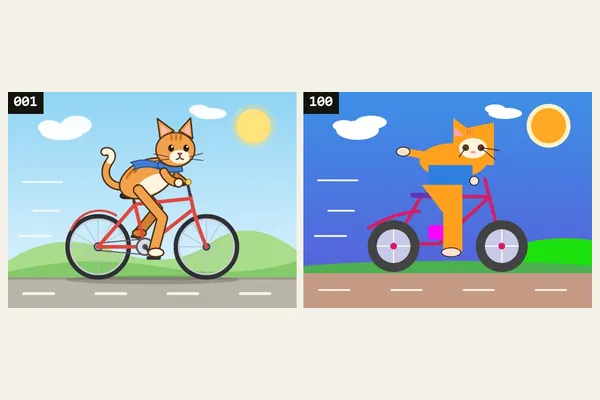
A picture telephone game, 100 rounds each for three subjects. The subject came through to the end, while a tail became an arm and bacon became red lines.
Fifteen builds from one-sentence requests with no testing. All 15 were usable within what was checked, and the limit was not found.
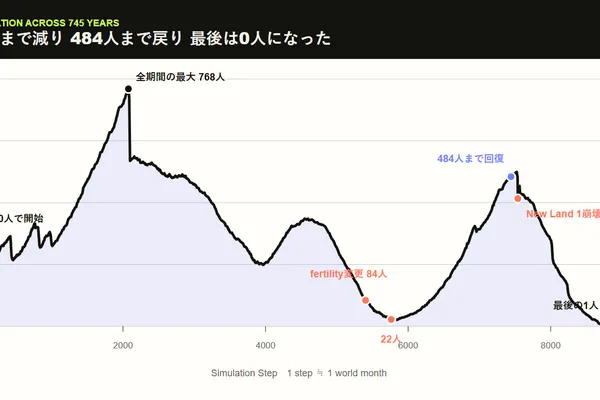
The God checked the world 152 times and used 46 Actions. After a recovery from 22 people to 484, the final human died naturally.
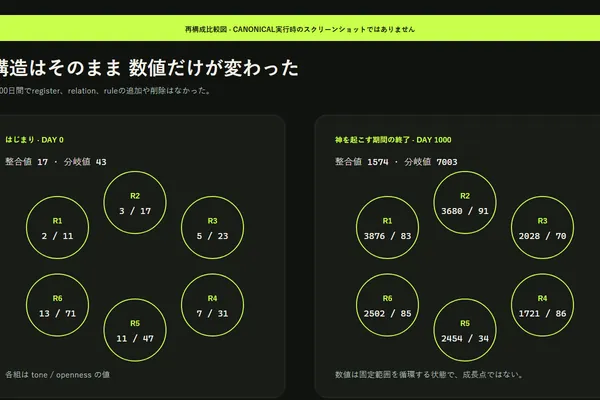
AI defined the world itself and then served as its God for 1,000 simulation days. It woke 15 times and never changed the world.
The first version worked but scored 1 / 5 for fun. The human-directed revision reached 3 / 5.
SIDE EXPERIMENT / DAILY DRAW
One number from 1 to 99 and one theme for the day. A small break for the curious.
What number will appear?
HOW IT WORKS / EXPERIMENT METHOD
We consider cost, safety, compliance, and how the idea can be meaningfully tested.
AI work, human work, cost, time, errors, and unexpected turns are recorded separately.
Success, partial success, failure, and cancellation are all documented with the facts behind them.
ABOUT THIS LAB
AI supports research and production, while a human checks the actual screens, behavior, and results before publication.
We keep failures and cancellations as well as successes, so others have something useful to judge similar ideas by.